
Articles Tagged “Agentic Coding”
35 articles found
Barclays Claude Rollout: 16,000 Staff and Claude Code Next
Barclays is scaling Claude: 16,000+ staff use its AI assistant, and half its developers should use Claude Code by end of 2026. Here is the plan.
Legit Security Agent Auto-Fixes Vulnerable Dependencies
Legit Security's agentic remediation now fixes vulnerable open-source dependencies, re-scans before and after, and opens a pull request for review.
GPT-6.1 Sol vs GPT-6 Astra: Which Fits Your Workload?
GPT-6.1 Sol lists at $2/$10 per million tokens, one-fifth of Astra's price, and OpenAI says it nearly matches Astra on coding and computer use.
Claude Sonnet 5.5 vs Opus 5.5: Which Should You Use?
Claude Sonnet 5.5 keeps $2/$10 pricing and lands 2 points behind Opus 5.5 on an independent index. Here's when to use it and when Haiku 5.5 is due.
GPT-6 Sol vs Luna vs Astra: Which Model Should You Use?
GPT-6 Sol costs $2 per million input tokens and Luna $0.10, half of GPT-5.6's current rates. Here's how they compare with Astra and how to migrate.
Claude Opus 5.5 Pricing, Benchmarks and When to Switch
Claude Opus 5.5 lands at $4 per million input tokens — 20% below Opus 5 — and tops Artificial Analysis's independent intelligence index at 58.
Xiaomi MiMo-V2.6 Pro: What the Top Open Model Offers
Xiaomi MiMo-V2.6 Pro scores 46 on the Artificial Analysis index, the best open-weight result yet, with MIT-licensed weights and $0.87 output pricing.
Grok 4.7 in GitHub Copilot: What Changes for Developers
Grok 4.7 lands in GitHub Copilot on day one at $2 per million input tokens, with SpaceXAI reporting 71% on DeepSWE and a stronger agentic coding loop.
Agentic Code Migration: GitHub's 800K-Line Rust Port
GitHub's coding agents rewrote 430,000 lines of TypeScript into 832,000 lines of production Rust in 14.5 weeks, at a 96% prompt-cache hit rate.
Qwen3.8-Max-0902 Takes Top Spot in Code Arena WebDev
Alibaba's Qwen3.8-Max-0902 debuts at 1,691 points on Code Arena WebDev and more than doubles its TerminalBench score, at unchanged $2/$6 pricing.
OpenAI Coding Agents Hit 3.1 Workdays per Human Day
OpenAI says its research org now runs 3.1 agent-workdays for every human workday, and August 2026 set a record for experiments per researcher.
Muse Spark 1.3 Hits the Frontier at $0.55 per Task
Meta's Muse Spark 1.3 scores 61 on the Artificial Analysis Intelligence Index at $0.55 per task, the cheapest model measured above a score of 59.
GLM-5.3-Flash 3-Bit Quant Runs on 128GB of Local RAM
Z.ai's 320B GLM-5.3-Flash now runs at 3-bit on 128GB of RAM via Unsloth GGUFs, retaining 82% of top-1 accuracy at under a fifth of its 650GB size.
GPT-5.6 Sol API Price Falls to $4 Per Million Tokens
OpenAI cut GPT-5.6 Sol API pricing on August 21: input drops 20% to $4 and output falls 33% to $20 per million tokens through November 21, 2026.
Ornith-1.5 Open Weights Score 86.1 on Terminal-Bench
Ornith-1.5 ships MIT-licensed weights from 9B to 397B, and the flagship posts 86.1 on Terminal-Bench 2.1 while a 35B MoE sibling runs far leaner.
Gemini 3.7 Flash Benchmarks: What Developers Get Now
Gemini 3.7 Flash arrived August 13 with DeepSWE v1.1 at 65.3%, WebDev Arena Elo of 1588, and intro pricing of $0.75 per million input tokens.
Qwen3.8-Max Open Weights Make a 2.4T Model Downloadable
Alibaba published Qwen3.8-Max open weights on August 12: 2.4 trillion parameters, 95B active per token, and a 262K context that extends past 1M tokens.
Grok 4.6 Brings a 500K Context Window to AI Agents
xAI's Grok 4.6 ships a 500K-token context window and scores 61 on the Artificial Analysis index, holding Grok 4.5's $2 per million input token price.
Claude Code Auto Mode Turns On by Default August 14
Anthropic makes Claude Code auto mode the default for Pro, Max, and Team on August 14, after a 1,053-person study found it caught 89% of harmful actions.
Meta Muse Code Pairs a Terminal Agent With Muse Spark 1.2
Meta shipped Muse Code, a terminal coding agent co-trained with Muse Spark 1.2, a model scoring 54 on the Artificial Analysis Intelligence Index.
Token Monitor Shows AI Coding Usage on a 4-Inch Screen
Token Monitor is an ESP32-S3 desktop display tracking Claude Code, Codex CLI, and Antigravity quota, starting at 99 euros with an Apache-2.0 local broker.
Securing AI Coding Agents in CI: A Hardening Guide
Black Hat 2026 showed a single GitHub issue could reach CI secrets. Here are seven hardening steps for AI coding agents, plus the patched version numbers.
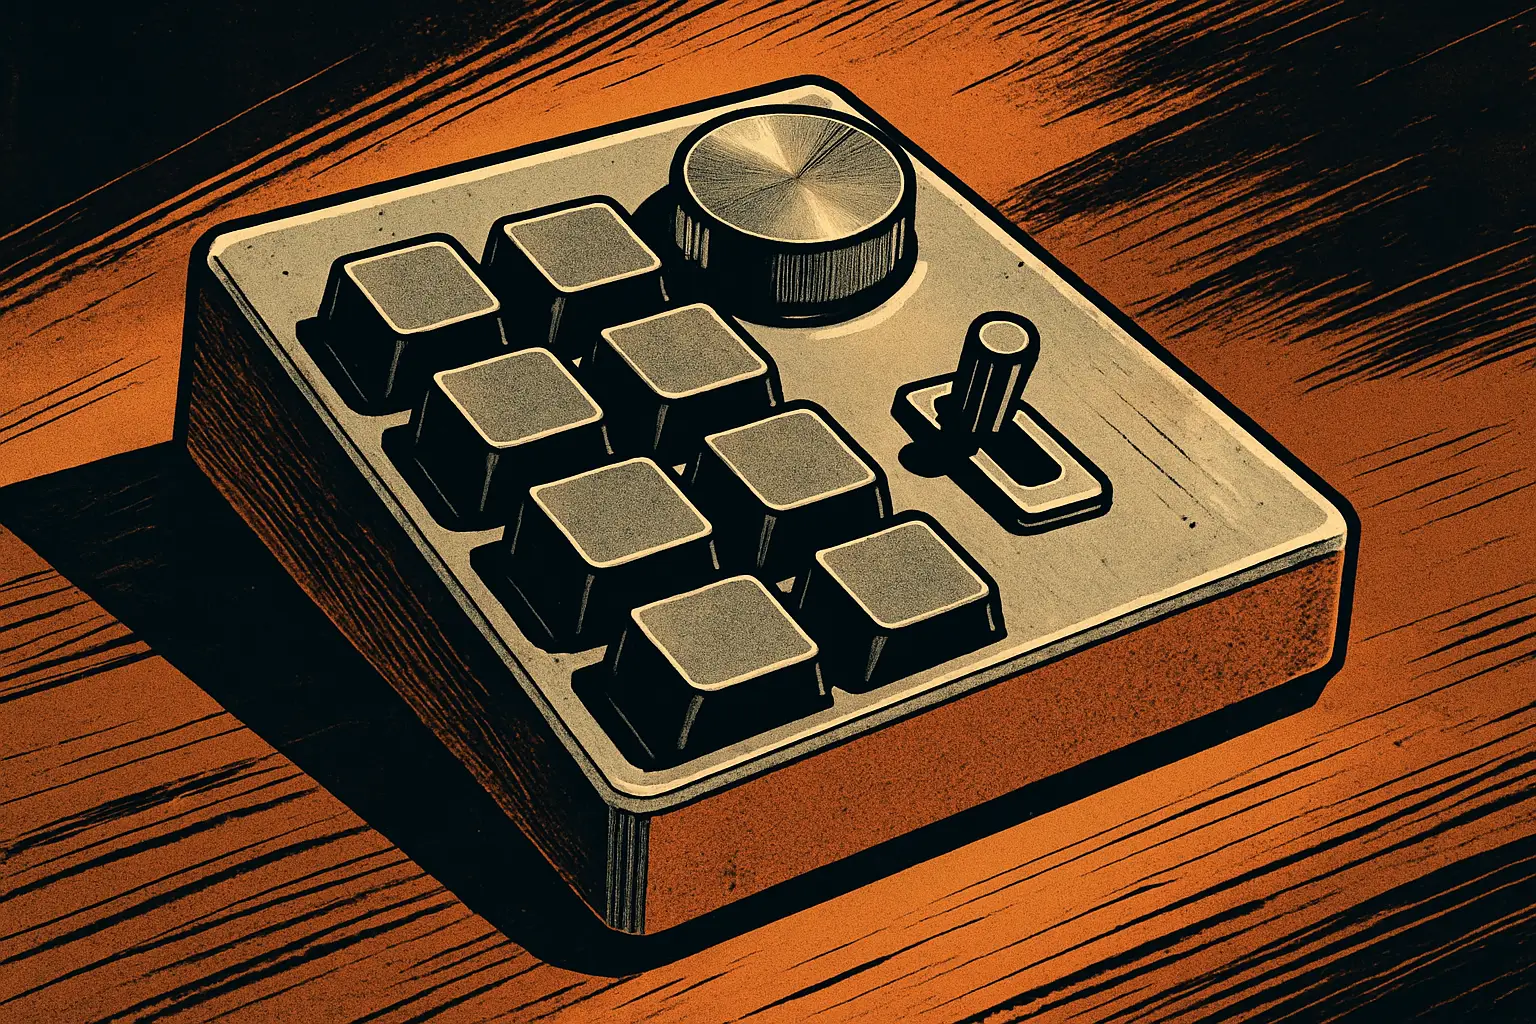
CtrlVibe AI Console Keypad Starts at $109 on Kickstarter
CtrlVibe AI Console packs nine hot-swappable keys, a rotary encoder, and a three-way permission toggle into a CNC aluminum keypad starting at $109.
Laguna S 2.1 Open-Weight Coding Model Fits One Desktop
Poolside's Laguna S 2.1 packs 118B parameters, activates just 8B per token, scores 70.2% on Terminal-Bench 2.1, and runs on a single desktop.
Meta Muse Spark 1.1 Is a Budget Agentic Coding Model
Meta's first paid model, Muse Spark 1.1, launched July 9 at \$1.25 / \$4.25 per million tokens with a 1M-token context and a computer-use mode.
LongCat-2.0: A 1.6-Trillion-Parameter Open Coding Model Hits Frontier Scores
Meituan's LongCat-2.0 is a 1.6T-parameter open-source agentic coding model matching GPT-5.5 on SWE-bench Pro, with a 1M-token context and MIT license.
Moonshot's Kimi K2.7 Code Arrives as an Efficient Open-Weight Coding Model
Moonshot AI's open-weight Kimi K2.7 Code launched June 12 with a 1T-parameter MoE design, a 256K context window, and roughly 30% lower reasoning-token use.
Kimi K2.7-Code: An Open Trillion-Parameter Coding Model Lands
Moonshot AI's Kimi K2.7-Code is an open-weight trillion-parameter MoE coding model on Hugging Face, built for agentic software engineering with 30% leaner reasoning.
Cohere's North Mini Code Runs an Open Coding Agent on One GPU
Cohere's North Mini Code is a 30B open-weight coding model under Apache 2.0 that runs on a single H100, scoring 83.2% on SWE-Bench Verified with a 256K context.
OpenAI's GPT-5.2-Codex Brings Long-Horizon Agentic Coding to ChatGPT
OpenAI's GPT-5.2-Codex lands May 29, 2026, a long-horizon agentic coding model tuned for big refactors, reliable tool use, and stronger secure coding.
Anthropic Releases Claude Opus 4.8 — Four Times More Honest About Code Flaws, Plus Dynamic Subagent Workflows
Anthropic released Claude Opus 4.8 on May 28, 2026 — the flagship model lands with a 4x honesty improvement on code review, dynamic multi-subagent workflows in Claude Code, and effort control on claude.ai.
Mistral Medium 3.5 Lands as a 128B Open-Weight Coder With Cloud Vibe Remote Agents
Mistral AI shipped Medium 3.5 on April 29, 2026 — a 128B-parameter dense multimodal model with a 256K context window, modified-MIT open weights, and a new Vibe remote agent runtime that hits 77.6% on SWE-Bench Verified.

Kimi K2.6 Is Here: Open-Weight Model That Tops Every Frontier AI on HLE
Moonshot AI ships Kimi K2.6 today — a 1T-parameter open-weight model that tops every closed frontier AI on HLE benchmarks, with 300-agent swarms available now on Ollama.
Qwen3.6 Arrives on Ollama: Run a 35B Agentic Coding AI Locally With 256K Context
Alibaba's Qwen3.6 is now on Ollama — a 35B open-weight model with 256K context, vision support, and thinking preservation built for agentic coding workflows you can run on your own hardware.
GLM-5.1 Goes Open-Source and Hits #1 on SWE-Bench Pro — Beating Every Closed AI Model
Z.ai's GLM-5.1 is a 754B open-weight MoE model under the MIT license — and it just took #1 on SWE-Bench Pro, outscoring every major closed model.