StateBench Explained: Where AI Loses Track in Long Documents
Ai2's StateBench tests how AI tracks changes across long documents, with sequences up to 64,000 steps and results showing why hybrid models hold up better.
Ask an AI model to summarize a long contract and it may do well. Ask it to follow a value through dozens of interdependent updates and the picture becomes more interesting. That is the question behind StateBench, a new benchmark published on November 3, 2026 by the Allen Institute for AI (Ai2). It measures long-context state tracking: how well language models keep up with information about entities as it changes over the course of a document.
- StateBench sorts state-tracking problems into four difficulty levels, from fixed values to values that depend on other values
- Ai2 tested Gemini 3.8 Flash, Claude Opus 5.5, GPT-6 Sol and GPT-6 Luna, and all performed well on the two easier levels
- On the longest problems at the hardest level, frontier accuracy fell to 13% or lower, according to Ai2
- Hybrid and Gated DeltaNet models trained directly on the task held up across tens of thousands of assignments
What Is Long-Context State Tracking?
State tracking underlies everyday reading and coding. A program reassigns a variable, or a character in a novel hands an object to someone else, and the reader must update their mental model. Ai2's framing uses variable assignment as the common language:
- R-trivial: a value never changes, like a birth date
- Aperiodic: only the latest value matters, like a thermostat setting
- Soluble: each update builds on the current value, like a running game score
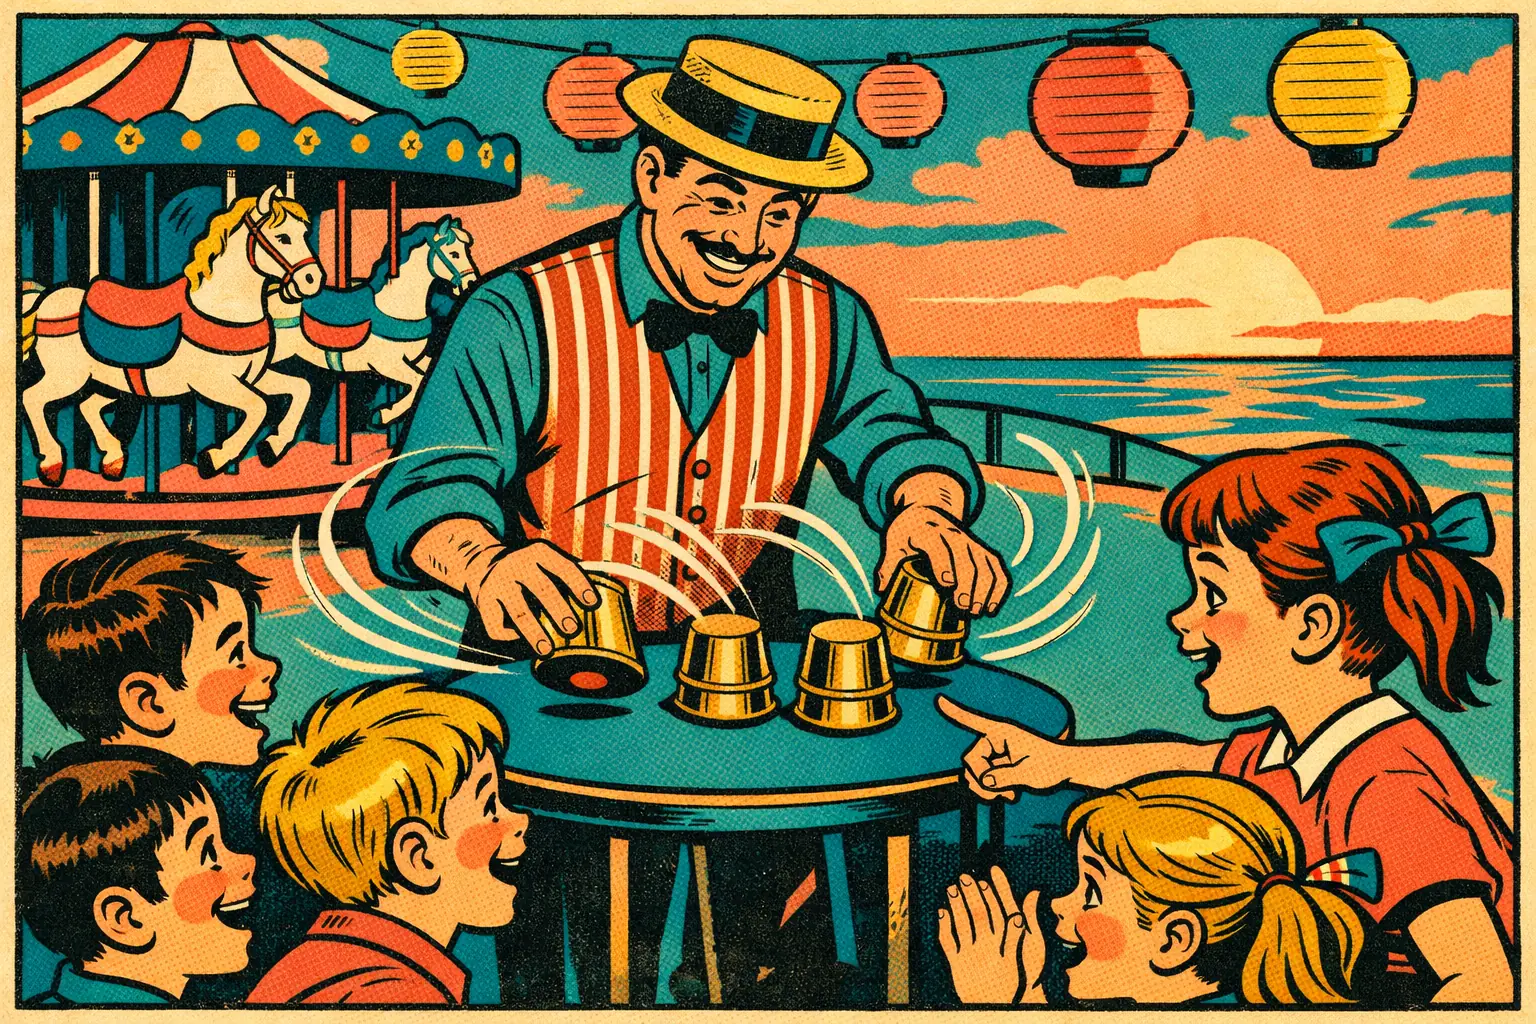
- General finite: one variable can take another's value, like tracking a ball under five swapped cups
These categories come from Krohn-Rhodes theory, a branch of algebra concerned with decomposing such problems into primitives. That theoretical grounding is what separates StateBench from earlier tests that concentrated mainly on the hardest cases.
What Did the StateBench Results Show?
The headline comparison is between architectures rather than vendors. Ai2 trained several 275-million-parameter models from scratch on sequences of up to 256 assignments, then tested them on sequences as long as 64,000 assignments, which is 250 times the training length.
Gated DeltaNet and hybrid models generalized almost perfectly on the three easier levels out to the longest sequences tested. Transformers learned the easier levels but degraded on longer inputs, and never learned the general finite level. On that hardest level, the more flexible Gated DeltaNet variant stayed near perfect to roughly 10 times its longest training sequence.
The researchers draw an encouraging conclusion from this. For Gated DeltaNet and hybrid models, the shortfall seen in pretrained versions appears to reflect training rather than architecture, which means better data could unlock skills these designs already have the capacity to learn. The frontier results are attributed to Ai2's own testing, and the team suggests sensitivity as one likely factor, since many more steps at the harder levels can affect the final answer.
Why Does This AI Benchmark Matter for Developers?
Benchmarks earn their value by naming a failure precisely enough to fix it. As with OpenAI's LifeVal benchmark for everyday tasks, the useful outcome here is a finer-grained map of what systems can do. If your application only needs the latest value of something, current models look strong. If it needs to carry a chain of dependent updates through a very long log, it is wise to add explicit state storage rather than rely on the model's context alone.
That last point is my own practical reading, not a recommendation from the paper, but it follows directly from where the accuracy curves separate.
What Questions Remain Open?
Ai2 is candid about the limits. StateBench assumes a fixed number of variables, while real conversations introduce new people and objects as they unfold. The exact capabilities of constrained Gated DeltaNet designs also remain unresolved, including the effect of combining them with attention layers. The team has released the tech report, data and code so others can extend the work. Follow more research like this in our AI coverage.
Sources: Ai2 on Hugging Face: StateBench — November 3, 2026.
More AI Stories
Google TPU 8i Max and 8tx: What Two New AI Chips Change
Google's TPU 8i Max doubles compute, SRAM and HBM bandwidth for million-token contexts, while TPU 8tx brings confidential computing to AI inference.
Counterfactual World Models Help Robots Learn From Surprises
A new counterfactual world model method lets robots ask what would have happened, lifting retry success to as high as 97 percent in simulated tests.
OpenAI Pierre Deal: What It Means for Codex and Code Review
OpenAI will acquire Pierre, maker of Code Storage plus Diffs and Trees, days after revealing Pando, a Git backend with nearly 5x faster pushes.