Optane PMem Homelab Runs Kimi K3 2.8T Model on CPU Alone
A homelab builder ran Moonshot's 2.8-trillion-parameter Kimi K3 on secondhand Optane PMem 200 and a 40-core Xeon, at 0.85 tokens per second with no GPU.
Here is a build that proves homelabbers never run out of creative ideas. According to Tom's Hardware, a Reddit user has run Moonshot AI's 2.8-trillion-parameter Kimi K3 model entirely on CPU, using discontinued second-generation Intel Optane Persistent Memory 200 modules instead of a pile of expensive DRAM or GPUs. It is slow, it is loud, and it is a genuinely clever path to running a frontier-scale open model at home.
- The build pairs a 40-core 3rd-gen Xeon Scalable CPU with Optane PMem 200 and no GPU for inference
- Tom's Hardware reports 0.85 tokens per second at 1-bit quantization and 0.75 tokens per second at 3-bit
- Even the smallest community quantization of Kimi K3 needs at least 610GB of memory
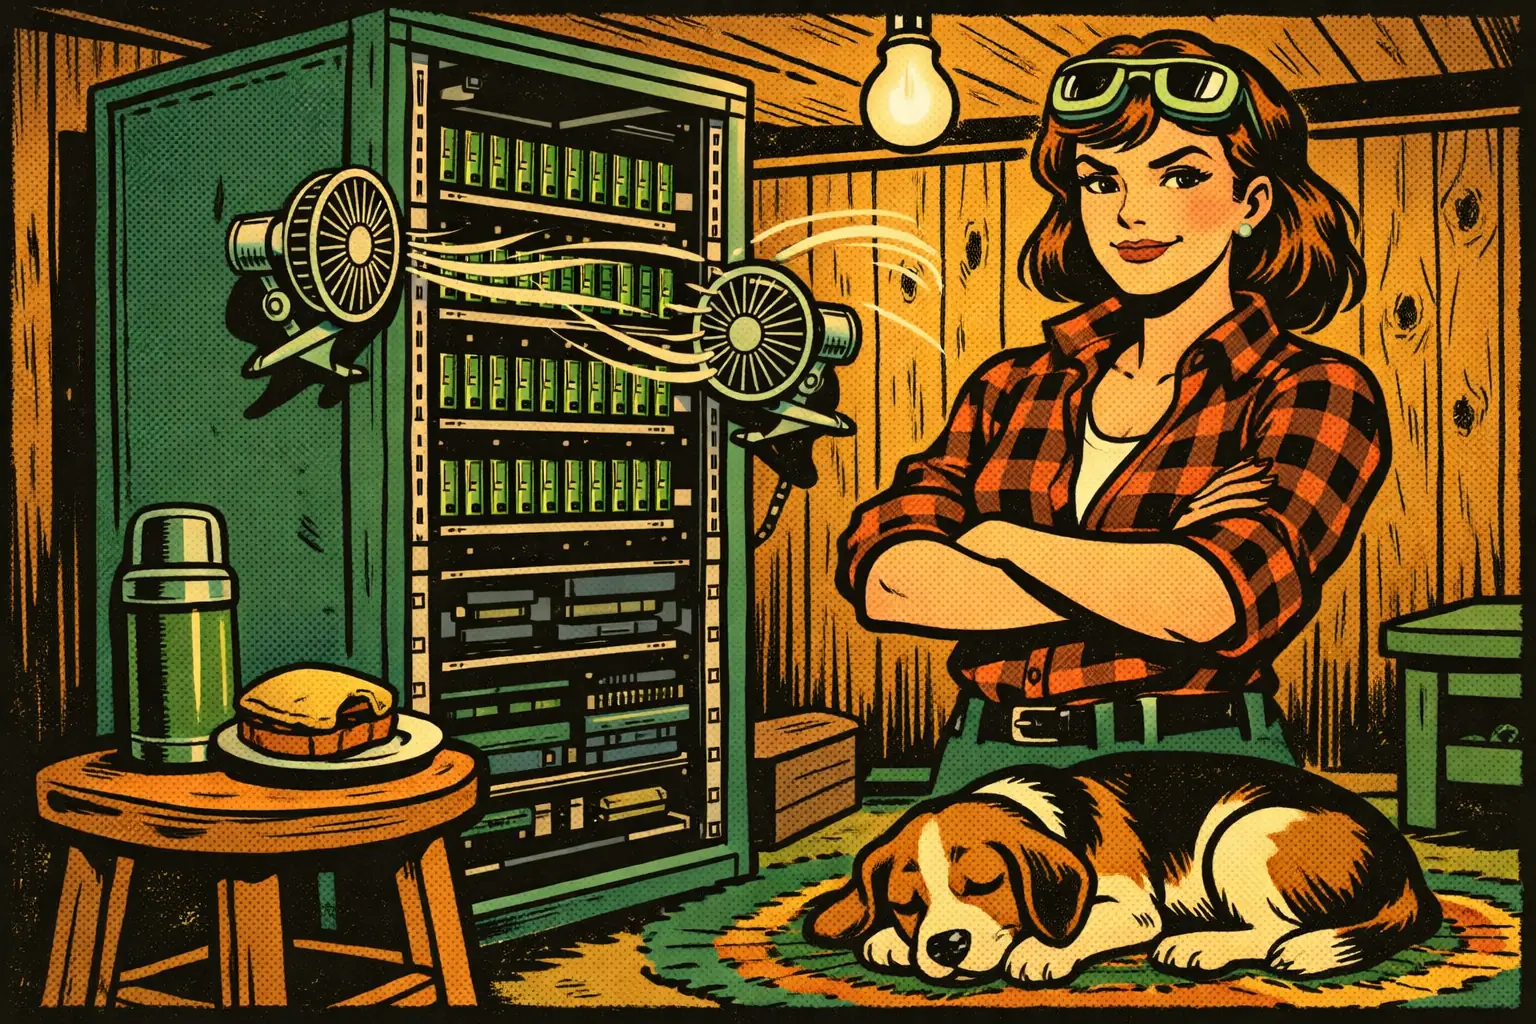
- The builder treats active DIMM cooling as mandatory, using dual 12W blower fans aimed at the modules
Why Use Optane Persistent Memory for Local LLMs?
Capacity is the whole game with trillion-parameter models. Kimi K3 is a data center model, and Moonshot recommends data center inference engines to run it. Reaching 610GB or more of memory with regular DDR4 or DDR5 is wildly expensive, especially with DRAM prices elevated this year. The builder told Reddit that secondhand Optane cost "a fraction" of the equivalent DRAM.
Intel launched the Optane PMem 200 series in 2020 for 3rd-gen Xeon Scalable processors, in 128GB, 256GB and 512GB modules. Tom's Hardware notes the second generation can deliver up to 32% more memory bandwidth on average than the first-gen PMem 100. Optane can run in Memory Mode, where DRAM acts as a cache in front of it, or App Direct Mode, which exposes Optane as a separate persistent region that software maps directly. This build uses App Direct, which gives more control over where the model's tensors live.
How Fast Is Kimi K3 on Optane?
Let's be clear: 0.85 tokens per second is not a chat experience. One Reddit commenter estimated a 50,000-token task could take around 13 hours. Another pointed out that overnight batch jobs, such as summarizing a document archive or generating test data, do not care much about speed. For comparison, an earlier first-gen Optane build ran the smaller 1-trillion-parameter Kimi K2.5 at roughly 4 tokens per second, with an RTX 3060 handling part of the model.
The good news is that these are pre-tuning numbers. The builder has not yet tuned thread counts or NUMA affinity, and plans to add GPUs and load parts of the model into DRAM as a faster tier, with more benchmarks to come.
What Cooling Do Optane DIMMs Need?
This is the most useful takeaway for anyone copying the idea. Under sustained inference, the Optane modules got extremely hot, enough that the builder warns they can endanger neighboring DRAM. Tom's Hardware explains that Intel rates the modules for forced airflow of 2.4 to 2.7 meters per second, a data center figure, with each module drawing 12W or 15W. Throttling kicks in at 83 degrees Celsius, with a thermal shutdown at 85. If you try this build, point dedicated fans straight at the memory.
For background on the model itself, read our coverage of the Kimi K3 open-weights release, and for another budget-memory trick see our GPU-less DDR3 local LLM server. More homelab builds live in our mini computers section.
Sources: Tom's Hardware — November 8, 2026.
More Mini Computers Stories
M5Stack Core Matrix: A $29.90 ESP32-C61 Board With 256 LEDs
M5Stack's Core Matrix pairs an ESP32-C61 with Wi-Fi 6, a 16x16 white LED matrix and a BMI270 IMU for $29.90, ready for Arduino and UIFlow2 projects.
What Is Wi-Fi HaLow? 802.11ah Range, Speed and Hardware
Wi-Fi HaLow (802.11ah) reaches about 1 km on sub-1 GHz spectrum at up to 43.3 Mbps. Learn how it works, how it compares to LoRa, and which boards to buy.
LattePanda Mu Ultra Benchmarks: Local LLMs on a $733 Kit
CNX Software's LattePanda Mu Ultra benchmarks show 13.59 tokens/s on a 3B Llama model, 411 FPS YOLO26n on the GPU, and what the $733 kit needs for cooling.