
Google AI Edge Gallery Adds Offline Speech: What Devs Get
Google AI Edge Gallery now runs speech recognition and text-to-speech fully on device, with 100+ languages and replies that start in about 100 ms.
Voice is the most natural way to talk to an AI assistant, and it is also the feature most likely to break the moment you lose signal. Google is tackling that head-on. In a November 10 post on the Google Developers Blog, later republished on Hugging Face, the Google AI Edge and Android ML teams added on-device automatic speech recognition (ASR) and text-to-speech (TTS) to Google AI Edge Gallery, the open-source showcase app for running AI models locally.
- Android speech: ML Kit transcription across 100+ languages at 10x real-time speed, built into the OS so it adds 0 MB to an app
- Fast replies: a few-step diffusion TTS model starts speaking in about 100 ms and produces 24 kHz audio at up to 50x real-time speed
- Cross-platform models: LiteRT bundles for Parakeet-TDT 0.6B, PocketTTS 100M, Kokoro-82M and Phonon 31M
- Pairing: works alongside on-device language models such as Gemini Nano and Gemma 4, fully offline
What Is New in Google AI Edge Gallery?
The update brings a complete local voice pipeline. On Android, developers can tap Google's system speech models through ML Kit, which keeps app sizes small because the models ship with the operating system. For web, desktop and other platforms, Google optimized open-weight speech bundles in its LiteRT format so they stream transcription and synthesize speech without fighting the language model for compute.
Inside the app itself, the AI Chat feature now offers streaming voice dictation and read-aloud playback. A floating TTS bar highlights each sentence as it is spoken, and you can tap any sentence to jump to it. Settings let you choose speech pipelines, voices and downloaded language packs in one place.
How Does the XR Language Teacher Demo Work?
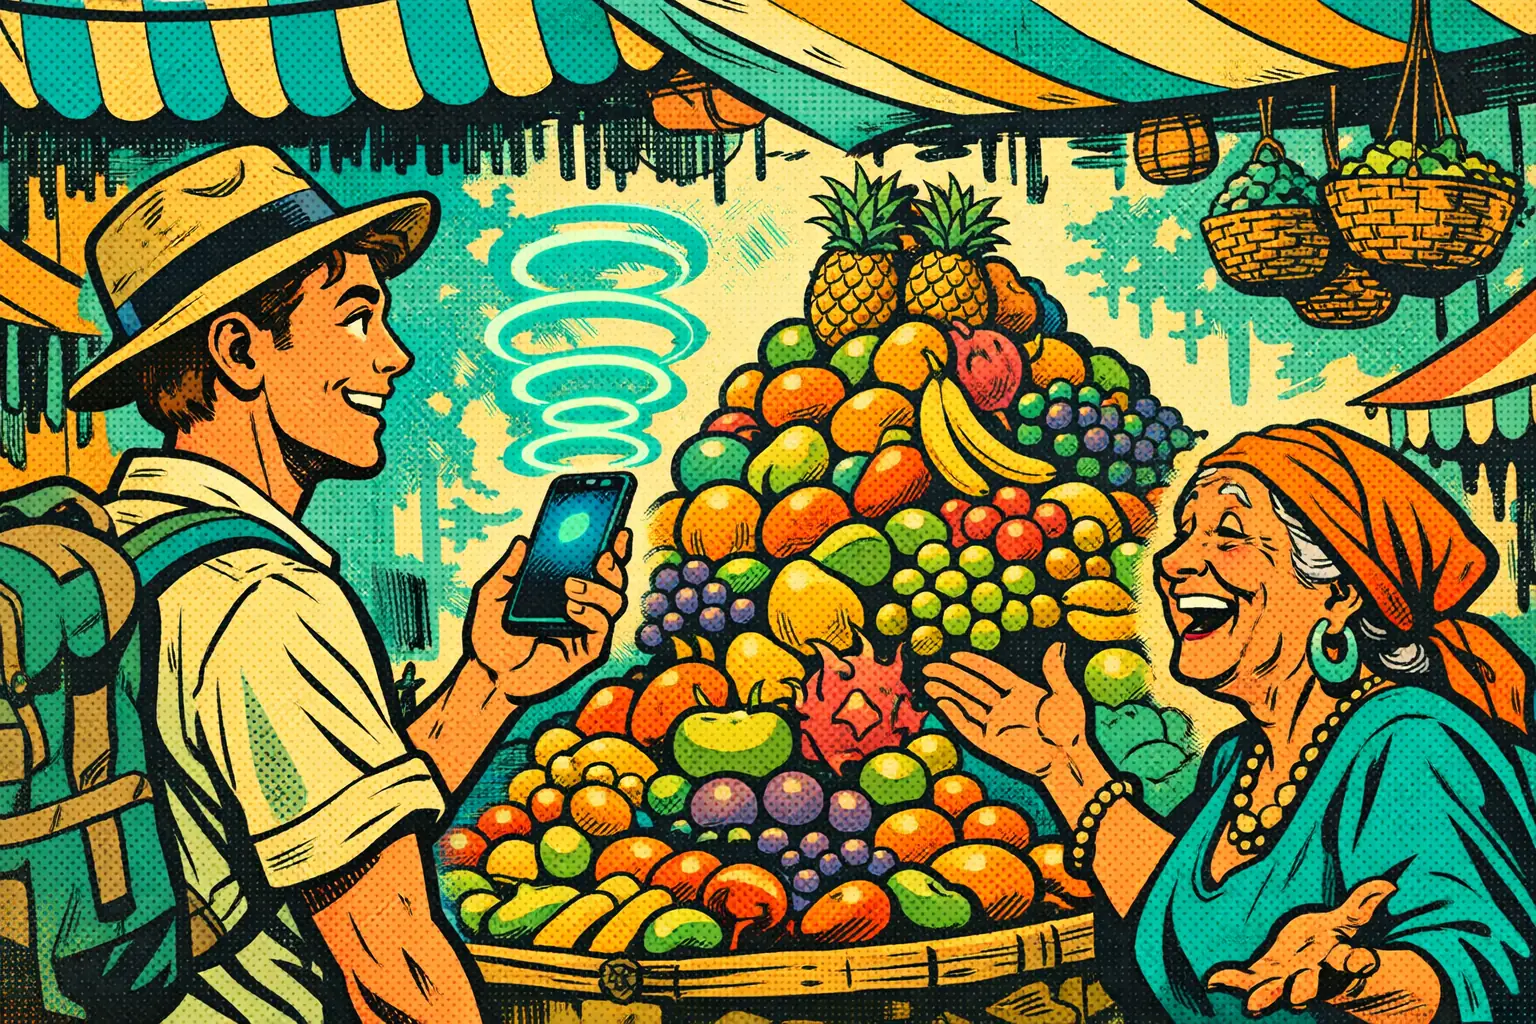
The headline showcase is XR Language Teacher, built for the traveler standing in a market with no Wi-Fi. You point the camera at an object or menu and ask aloud what it is and how to request one. On-device ASR streams your question together with the camera frame to Gemini Nano on Android, or Gemma 4 on other platforms, in a single pass.
The clever part is bilingual speech. The model uses a structured output format to explain the scene in your language while tagging the foreign phrases separately, so the TTS engine can switch voices and accents mid-sentence and pronounce the local words authentically. Because everything runs on a paired phone, Google says the same experience extends to hands-free smart glasses, which lines up with the company's recent intelligent eyewear launch.
Why On-Device Voice AI Matters for Developers
Running speech locally solves three problems at once: privacy, because audio never leaves the device; latency, because there is no round trip; and reliability, because it works underground or abroad. Google's open-source code also shows practical details that usually take weeks to figure out, such as stripping Markdown and skipping code blocks before reading a reply aloud, and scheduling speech synthesis at the sentence level so it does not stall token generation.
For anyone building local assistants, this is a ready-made reference design. Pair it with what we have seen from Gemma 4 on Apple Silicon, and the fully offline, voice-first assistant is starting to look like a weekend project rather than a research effort. Find more in our AI coverage.
Sources: Google Developers Blog — November 10, 2026; Hugging Face (LiteRT Community) — November 12, 2026; Google AI Edge Gallery on GitHub — project repository.
More AI Stories
Gemini Google Wallet Integration: AI Budgeting Explained
Gemini can now read your Google Wallet spending to chart budgets, flag pricier subscriptions and plan holiday costs. Here's how the US rollout works.
XYBench: Why AI Assistants Miss the Real Question You Ask
Ai2's XYBench tests 8,115 misguided questions to see if AI assistants spot the real problem. The award-winning benchmark shows where models can improve.
SOV-Transcribe-1: Salesforce's Open Speech Model Explained
Salesforce's SOV-Transcribe-1 is an Apache 2.0 open-weight speech-to-text model with a 2.28% word error rate, style steering and 7 languages.